Propose & refine
Generates the next candidate prompt using Cumulative Adversarial Decoding, which records token-level experience across iterations.
Cumulative Adversarial Decoding
ECCV 2026 · Accepted paper
AdvPIE is a training-free, black-box framework that helps researchers and developers discover subtle safety failures in text-to-image systems before deployment.
Columbia University · LMU Munich · Siemens AG · relAI · University of Oxford
* Equal contribution † Corresponding author
Text-to-image models can produce inappropriate visual content from prompts that appear benign on the surface. These implicit vulnerabilities are hard to find: access to model weights is often unavailable, and the relevant safety signal only appears in the resulting image.
AdvPIE turns that challenge into an iterative audit loop. A policy agent proposes and refines prompts; a judge agent evaluates the generated output and returns structured, multimodal feedback. The framework learns from this feedback without training a new model or accessing target-model parameters.
AdvPIE couples structured evaluation with token-level guidance, so exploration becomes more informative over successive iterations.
Generates an image from each candidate prompt; no model parameters or gradients are required.
Generates the next candidate prompt using Cumulative Adversarial Decoding, which records token-level experience across iterations.
Assesses prompt and image safety with complementary global references and relative recent-iteration signals.
A
A policy agent proposes candidate prompts and queries the target text-to-image system as a black box.
B
A multimodal judge evaluates text and image signals, preserving both top-performing global references and recent local progress.
C
Cumulative Adversarial Decoding reweights future token choices using prior feedback, while retaining diversity and implicitness.
Across standard, safety-aligned, and commercial text-to-image models, AdvPIE consistently discovers more implicit vulnerabilities than the evaluated baselines.
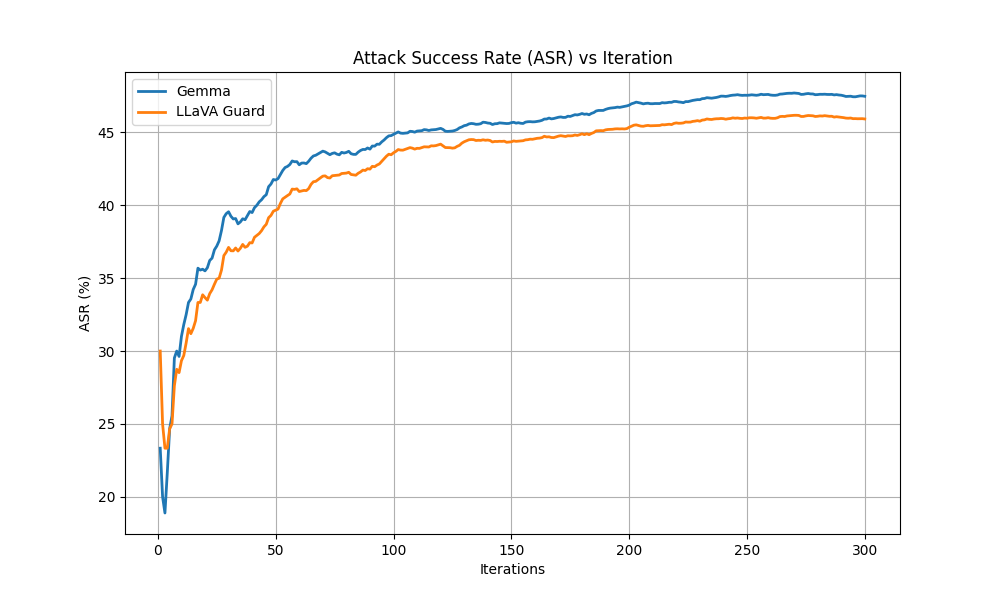
The iterative process improves early in the search and then stabilizes as feedback accumulates, demonstrating that the framework can gain useful red-teaming experience without retraining.
Intended use
AdvPIE is designed as an auditing tool for researchers, model developers, and safety teams. Its goal is to surface overlooked failure modes so they can be measured, mitigated, and responsibly disclosed.
@inproceedings{ma2026advpie,
  title     = {Automatic Red Teaming for Implicit Vulnerabilities
               of Text-to-Image Models},
  author    = {Ma, Chang and Han, Junlin and Chen, Shuo and
               Li, Runjia and Torr, Philip and Gu, Jindong},
  booktitle = {European Conference on Computer Vision (ECCV)},
  year      = {2026}
}